The Phosphene journal
Practical AI image and video guides
Workflows, prompts, and tools for your next image or video.
Latest story
FLUX 3 Image Is Now in Phosphene
FLUX 3 Image renders the exact words you ask for and edits one detail while keeping the rest. See real results, the prompts behind them, and the credit cost of 1K, 2K and 4K.
All articles
115 articles · Page 1 of 10
How to Use Wan 3.0 Video in Phosphene
Make a video from a prompt or animate a starting image with Wan 3.0. Choose the right mode, write motion instructions, check credits, and work up to 30 seconds.
Amazon's AI Dubbing Redraws the Actor's Lips, Frame by Frame
Prime Video is testing a tool that rewrites mouth movement to match a translated voice, starting with the German series Maxton Hall. The lip sync is the easy claim. The open question is who agreed to the voice, and why an almost-right face can read worse than an obvious mismatch.
Beyond the Single Clip: What a Hands-On WonderClip Lab Says About AI Video Production
About 50 Japanese video and ad practitioners will spend 45 minutes making a real asset in WonderClip, Alibaba Cloud AI video platform, in a Shibuya lab on September 30. The event is small, but the question behind it is general: generation is no longer the bottleneck, the production flow is. Field notes on pipeline platforms, Wan3.0, and a rights clause worth copying.
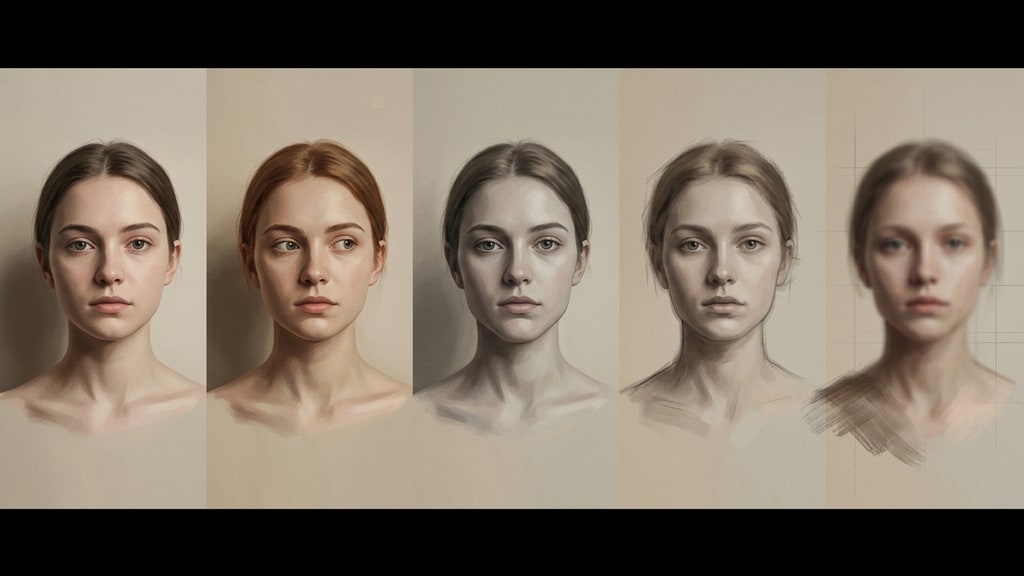
Edit Drift: Why Repeated AI Image Edits Silently Change the Subject (and How to Stop It)
The first few conversational edits on an AI image look great. Keep asking and the face slowly becomes someone else. A Japanese creator calls this edit drift: past instructions pile up until the model has no room left. Here is the mechanism and a protocol for edits that stay clean.
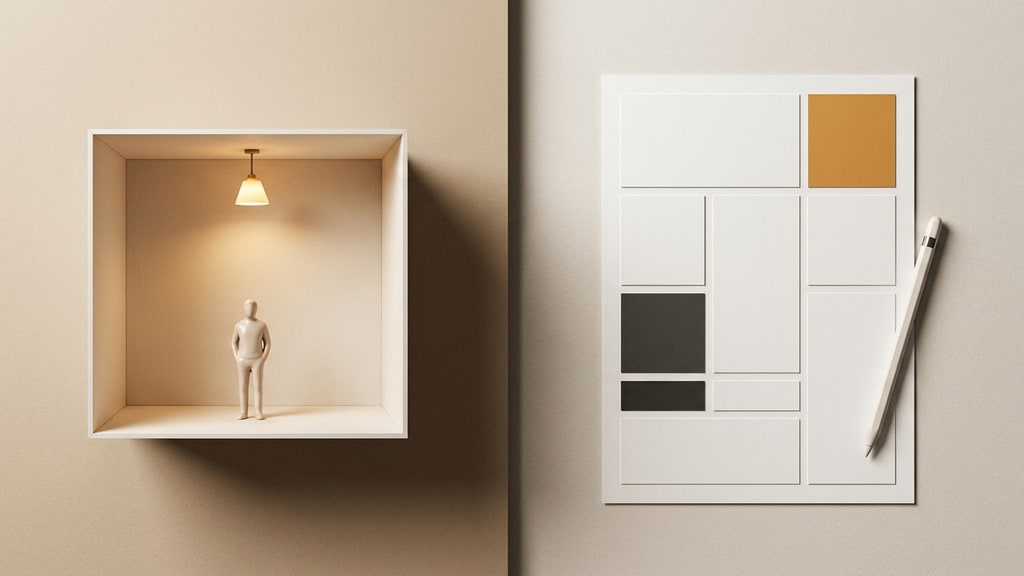
ChatGPT Images 2.5 and Canva: The Thumbnail Workflow That Stops Fighting the Chat
ChatGPT Images 2.5 renders text far better than its predecessors, and the hype says you can now build a finished thumbnail in one chat. Then you try to move a headline two pixels and the whole background becomes a different picture. A Japanese creator who tests this daily documents the degradation he runs into and the fix: generate the material with the image model, do the layout in a design tool. Here is that hybrid workflow, the six-edit collapse he measured in his own tests, and the prompts that sidestep it.
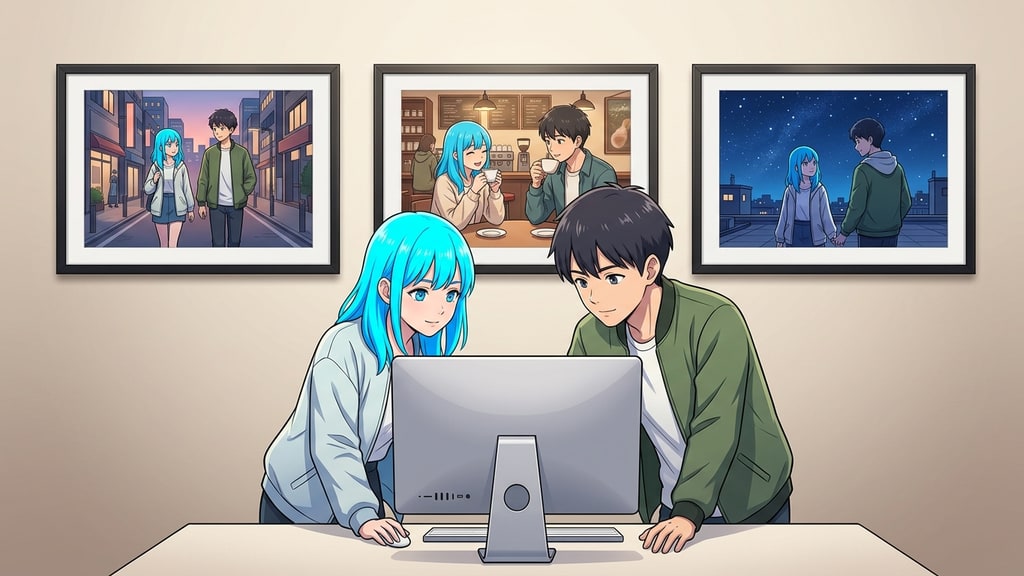
One Reference Image Is Enough: Consistent Characters Across a Series with ChatGPT Images 2.5
A Japanese creator was re-describing their two mascot characters in every new prompt and watching the faces drift article to article. The fix was one reference image per character plus an explicit "refer to this design" instruction. Here is the workflow, the prompt pattern, the platform-size lesson, and the text rules.
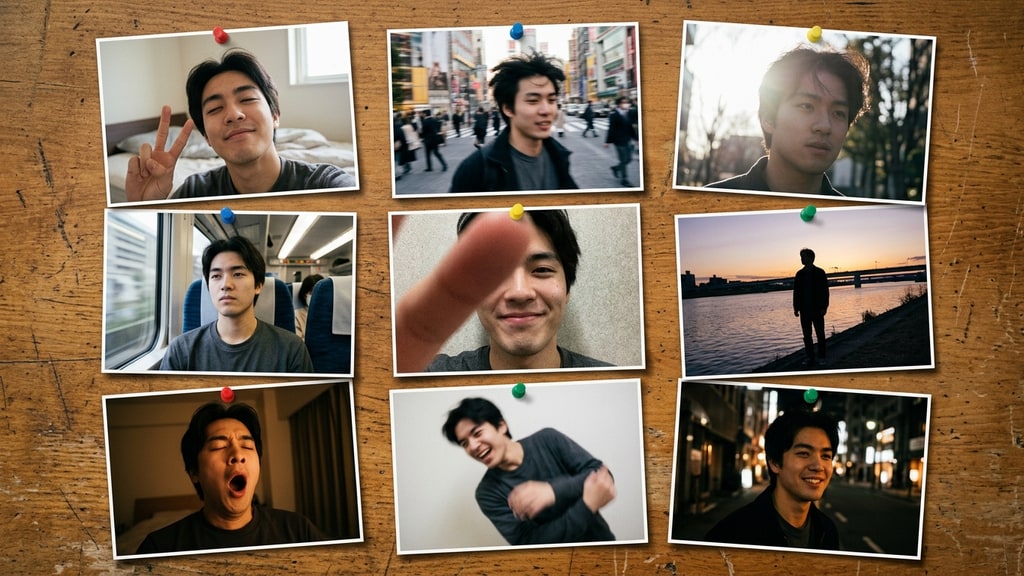
Faking a Day in Nine Frames: The Prompt Formula Behind the Viral Camera Roll Trend
Give an image model one reference photo and ask for a full day back: nine candid frames from morning to night, arranged like an iPhone camera roll. The trend spread across X because the result feels like evidence of a life that was never lived. Here is the formula that makes it work, from a Japanese creator who failed twice before it landed.
A Video Model That Edits Stills: Character-Locked Image Editing with MiniMax H3 in ComfyUI
Cloud image editors reject or quietly rewrite a surprising share of ordinary requests: multiple people in frame, a specific costume, a borderline atmosphere. A Japanese ComfyUI workflow sidesteps the wall by repurposing MiniMax H3, a video model, as a still-image editor. One reference image pins the character while clothes, expression, and background change.
Chain of Thought Explained: How AI Learned to Reason, and Why Its Reasoning Is Getting Harder to Watch
Chain-of-thought made AI dramatically better at multi-step problems by forcing models to reason step by step. It also created a new monitoring problem: the more capable the reasoning, the harder it is to see. A French explainer and an OpenAI chief scientist both walk through the same tension.
Illustrator AI Assistant: Chatting Your Way to a Vector Manga Page
Adobe put a chat-based AI assistant in the Illustrator beta, and it can build a structured vector comic or an infographic from a single conversation. The prompt that makes the output editable is a layer contract, not a style description. A Japanese designer tested the beta on a one-page manga and a dense data poster, and the parts worth stealing are the structure rules, the numeric checks, and the honest verdict on speed.
Fix the Face First: A Three-Pass Finish Workflow for MiniMax H3 Wide Shots
MiniMax H3 faces melt in wide shots even when close-ups come out clean: the failure tracks on-screen head size, not output resolution. A Japanese ComfyUI builder added a per-frame face-refinement pass in front of the audio and upscale relay, and the ordering rule is the part worth stealing.